Estimating Peat Subsidence with BLUE#
We start by assuming a linear model that describes the movement with an offset and a linear trend, and estimate these with Best Linear Unbiased Estimation (BLUE).
Data#
We have two independent measurement techniques that observe the same parcel:
InSAR |
Extensometer |
|
|---|---|---|
What is measured |
Average height change of the whole parcel (radar satellite) |
Height change at one point in the parcel (instrument in a borehole) |
Sampling |
every 6 days (some epochs missing due to lack of coherence) |
daily |
Precision |
\(\sigma_{\text{InSAR}} = 3\) mm |
\(\sigma_{\text{ext}} = 8\) mm |
For both datasets you may assume that the observations are normally distributed and independent, with the standard deviations given in the table.
In addition, the file weather.csv contains daily precipitation and evapotranspiration for the area. We will only use it to help interpret the results this week; next week it becomes part of the model.
All files are in the folder data/. Every file has a column Day, which is the number of days since 1 January 2019 (the first day of the weather record, which starts one year before the observations). You can use it to link observations to the weather.
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
from scipy.stats import norm
from scipy.stats.distributions import chi2

np.set_printoptions(precision=3)
Part 1#
Download and read the data
import os
from urllib.request import urlretrieve

def findfile(fname):
    if not os.path.isfile(fname):
        print(f'Downloading {fname}...')
        urlretrieve('https://github.com/TUDelft-MUDE/source-files/raw/main/file/GA1.7/'+fname, fname)

findfile('insar_observations.csv')
findfile('extensometer_observations.csv')
findfile('weather.csv')
Downloading insar_observations.csv...
Downloading extensometer_observations.csv...
Downloading weather.csv...
insar = pd.read_csv('insar_observations.csv')
ext = pd.read_csv('extensometer_observations.csv')
weather = pd.read_csv('weather.csv')

dates_insar = pd.to_datetime(insar['Dates'])
day_insar = insar['Day'].to_numpy()
y_insar = insar['Observations[m]'].to_numpy() * 1000      # mm

dates_ext = pd.to_datetime(ext['Dates'])
day_ext = ext['Day'].to_numpy()
y_ext = ext['Observations[m]'].to_numpy() * 1000          # mm

dates_weather = pd.to_datetime(weather['Dates'])
P = weather['Precipitation[mm]'].to_numpy()                # mm/day
E = weather['Evapotranspiration[mm]'].to_numpy()           # mm/day


sigma_insar = 3   # mm
sigma_ext = 8     # mm
Task 1.1:
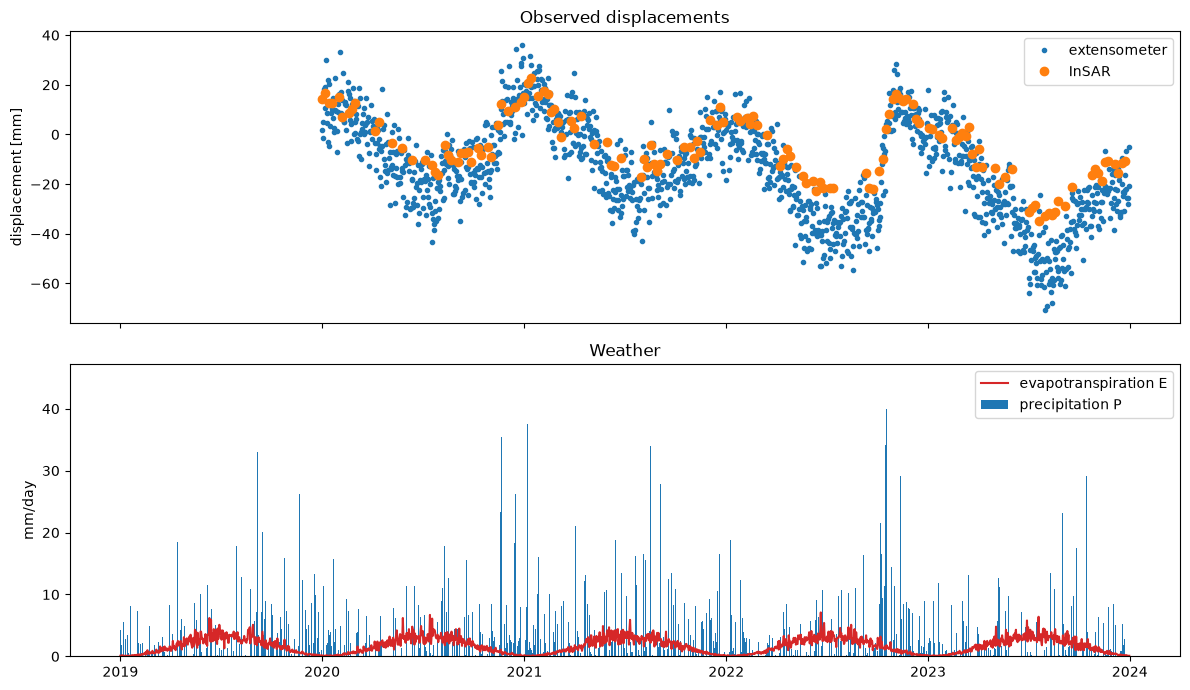
Investigate the two displacement datasets: print some summary statistics (number of observations, first and last date, minimum, maximum, …) and plot both time series in one figure. Also make a plot of the precipitation (P) and evapotranspiration (E).
Describe the two datasets in your own words. Consider at least:
the differences in sampling and precision;
what each technique physically observes (what could be the reason the plots of the two measurements are slightly different);
the patterns you see in the time series.
Note down your findings
# Print summary statistics of both displacement datasets
def print_summary(name, dates, y):
    '''Print simple summary statistics of a displacement time series.'''
    print(f'--- {name} ---')
    print(f'number of observations : {len(y)}')
    print(f'first / last date      : {dates.iloc[0].date()} / {dates.iloc[-1].date()}')
    print(f'min / max [mm]         : {y.min():.1f} / {y.max():.1f}')
    print(f'mean / std [mm]        : {y.mean():.1f} / {y.std():.1f}')
    print(f'median time step [days]: {np.median(np.diff(dates).astype("timedelta64[D]").astype(int))}')
    print()

print_summary('InSAR', dates_insar, y_insar)
print_summary('Extensometer', dates_ext, y_ext)

# Plot both time series in one figure, and the weather data in a second figure


fig, ax = plt.subplots(2, 1, figsize=(12, 7), sharex=True)
ax[0].plot(dates_ext, y_ext, '.', label='extensometer')
ax[0].plot(dates_insar, y_insar, 'o', label='InSAR ')
ax[0].set_ylabel('displacement [mm]')
ax[0].legend()
ax[0].set_title('Observed displacements')
ax[1].bar(dates_weather, P, width=1, color='tab:blue', label='precipitation P')
ax[1].plot(dates_weather, E, color='tab:red', label='evapotranspiration E')
ax[1].set_ylabel('mm/day')
ax[1].legend()
ax[1].set_title('Weather')
plt.tight_layout()
--- InSAR ---
number of observations : 145
first / last date      : 2020-01-01 / 2023-12-23
min / max [mm]         : -34.7 / 22.9
mean / std [mm]        : -5.0 / 13.1
median time step [days]: 6.0

--- Extensometer ---
number of observations : 1461
first / last date      : 2020-01-01 / 2023-12-31
min / max [mm]         : -70.7 / 36.2
mean / std [mm]        : -13.5 / 19.2
median time step [days]: 1.0
Solution 1.2:
The extensometer has more observations (1461, daily) versus the InSAR observation, (145 every 6 days, with some missing epochs) The InSAR data has better precision (\(\sigma\) = 3 mm versus 8 mm for the extensometer). Some InSAR epochs are missing (gaps of up to 24 days); the extensometer record is complete.
InSAR gives the average movement of the whole parcel; the extensometer measures more locally at one spot. Both describe the same parcel, but there is no reason why one spot should behave exactly like the average of the parcel.
Both series go down over the 4 years (roughly 25-40mm/4yr is roughly 5-10 mm/yr), but the movement is far from a straight line: every year the surface goes down in spring/summer and up again in autumn/winter, with an amplitude of several centimetres. The drops coincide with the periods where evapotranspiration is high and there is little rain. The extensometer shows larger up- and downward movements than InSAR.
The weather data show that evapotranspiration has a strong seasonal cycle (high in summer, almost zero in winter), while precipitation is more evenly spread over the year.
Part 2: Functional model#
We start with the simplest model for the height change \(d\) at time \(t\): an offset and a constant velocity,
where \(d_0\) [mm] is the relative surface height at \(t=0\) and \(v\) [mm/year] is the velocity. We define \(t\) in years since 1 January 2020 (the first observation epoch), so that \(d_0\) refers to the same moment for both datasets.
We fit this model separately to the InSAR data and to the extensometer data.
Task 2.1:
Compute the time \(t\) in years for both datasets and set up the design matrices
A_insarandA_ext.Hint: the column
Dayis the number of days since 1 January 2019; 1 January 2020(first day of extensometer and InSAR observations) is day 365. Use 365.25 days per year.
day_0 = 365
t_insar = (day_insar - day_0) / 365.25
t_ext = (day_ext - day_0) / 365.25

A_insar = np.column_stack([np.ones(len(t_insar)), t_insar])
A_ext = np.column_stack([np.ones(len(t_ext)), t_ext])

print('First 3 rows of A_insar:\n', A_insar[:3])
print('First 3 rows of A_ext:\n', A_ext[:3])
First 3 rows of A_insar:
 [[1.    0.   ]
 [1.    0.016]
 [1.    0.033]]
First 3 rows of A_ext:
 [[1.    0.   ]
 [1.    0.003]
 [1.    0.005]]
Task 2.2:
Answer the following questions (use the code cell to compute the numbers):
Write down the unknown parameters of the functional model, and their units
How many observations \(m\) and unknowns \(n\) are there for each dataset?
Make sure to note down your findings with pen and paper
print(f'Insar: m = {A_insar.shape[0]}, n = {A_insar.shape[1]}, redundancy = {A_insar.shape[0] - A_insar.shape[1]}')

print(f'Extensometer: m = {A_ext.shape[0]}, n = {A_ext.shape[1]}, redundancy = {A_ext.shape[0] - A_ext.shape[1]}')
Insar: m = 145, n = 2, redundancy = 143
Extensometer: m = 1461, n = 2, redundancy = 1459
Solution 2.2:
The unknowns are the offset \(d_0\) [mm] and the velocity \(v\) [mm/year].
InSAR: \(m = 145\), \(n = 2\). Extensometer: \(m = 1461\), \(n = 2\).
Part 3: Stochastic model#
The stochastic model describes the precision of the observations with the covariance matrix \(\Sigma_Y\).
Task 3.1:
Set up the covariance matrices
Sigma_Y_insarandSigma_Y_ext.Print the shapes of the covariance matrices
Print the first 3x3 entries
Sigma_Y_insar = sigma_insar**2 * np.eye(len(y_insar))
Sigma_Y_ext = sigma_ext**2 * np.eye(len(y_ext))


print('shape of Sigma_Y_insar:', Sigma_Y_insar.shape)
print('shape of Sigma_Y_ext:', Sigma_Y_ext.shape)
print('Sigma_Y_insar (first 3x3):\n', Sigma_Y_insar[:3, :3])
print('Sigma_Y_ext (first 3x3):\n', Sigma_Y_ext[:3, :3])
shape of Sigma_Y_insar: (145, 145)
shape of Sigma_Y_ext: (1461, 1461)
Sigma_Y_insar (first 3x3):
 [[9. 0. 0.]
 [0. 9. 0.]
 [0. 0. 9.]]
Sigma_Y_ext (first 3x3):
 [[64.  0.  0.]
 [ 0. 64.  0.]
 [ 0.  0. 64.]]
Task 3.2:
What is the dimension of both \(\Sigma_Y\) matrices?
What value is on the diagonal for both \(\Sigma_Y\) matrices?
note down your findings with pen and paper
Solution 3.2:
\(\Sigma_Y\) is \(m \times m\): 145× 145 for InSAR and 1461 × 1461 for the extensometer.
weights on the diagonals are Insar \(\Sigma_Y\) = 9 and Extensometer \(\Sigma_Y\) = 64.
Part 4: Apply Best Linear Unbiased Estimation#
Task 4.1:
Complete the function
BLUEbelow and use it to estimate the unknown parameters and the parameter covariance matrix for both datasets.
print the unknown parameters
print the covariance matrix of the parameters
note down the your computations and outcome on paper
def BLUE(A, y, Sigma_Y):
    '''Best Linear Unbiased Estimator.

    Input:  A, y , Sigma_Y
    Output: xhat , Sigma_Xhat
    '''
    inv_Sigma_Y = np.linalg.inv(Sigma_Y)
    Sigma_Xhat = np.linalg.inv(A.T @ inv_Sigma_Y @ A)
    xhat = Sigma_Xhat @ A.T @ inv_Sigma_Y @ y
    return xhat, Sigma_Xhat

xhat_insar, Sigma_Xhat_insar = BLUE(A_insar, y_insar, Sigma_Y_insar)
xhat_ext, Sigma_Xhat_ext = BLUE(A_ext, y_ext, Sigma_Y_ext)
print('InSAR estimates:')
print(f'd0 = {xhat_insar[0]:.4f} +/- {np.sqrt(Sigma_Xhat_insar[0, 0]):.4f} mm')
print(f'v  = {xhat_insar[1]:.4f} +/- {np.sqrt(Sigma_Xhat_insar[1, 1]):.4f} mm/yr')
print()
print('Extensometer estimates:')
print(f'd0 = {xhat_ext[0]:.4f} +/- {np.sqrt(Sigma_Xhat_ext[0, 0]):.4f} mm')
print(f'v  = {xhat_ext[1]:.4f} +/- {np.sqrt(Sigma_Xhat_ext[1, 1]):.4f} mm/yr')
print()

print("InSAR Sigma_X:\n", Sigma_Xhat_insar)
print("Extensometer Sigma_X:\n", Sigma_Xhat_ext)
InSAR estimates:
d0 = 6.0032 +/- 0.5033 mm
v  = -5.3694 +/- 0.2142 mm/yr

Extensometer estimates:
d0 = 2.3684 +/- 0.4184 mm
v  = -7.9470 +/- 0.1813 mm/yr

InSAR Sigma_X:
 [[ 0.253 -0.094]
 [-0.094  0.046]]
Extensometer Sigma_X:
 [[ 0.175 -0.066]
 [-0.066  0.033]]
Part 5: Model predictions and residuals#
Compute the estimated observations \(\hat{Y}\) and the residuals \(\hat{\epsilon}\).
Task 5.1:
Complete the function
get_resultsto compute \(\hat{Y}\), \(\hat{\epsilon}\) and the standard deviations of both.
def get_results(A, y, Sigma_Y, xhat, Sigma_Xhat):
    yhat = A @ xhat
    ehat = y - yhat
    Sigma_Yhat = A @ Sigma_Xhat @ A.T
    Sigma_ehat = Sigma_Y - Sigma_Yhat
    std_yhat = np.sqrt(np.diag(Sigma_Yhat))
    std_ehat = np.sqrt(np.diag(Sigma_ehat))
    return yhat, ehat, std_yhat, std_ehat

yhat_insar, ehat_insar, std_yhat_insar, std_ehat_insar = get_results(
    A_insar, y_insar, Sigma_Y_insar, xhat_insar, Sigma_Xhat_insar)
yhat_ext, ehat_ext, std_yhat_ext, std_ehat_ext = get_results(
    A_ext, y_ext, Sigma_Y_ext, xhat_ext, Sigma_Xhat_ext)
Task 5.2:
Complete the function
plot_resultsbelow by computing the 98% confidence intervals of \(\hat{Y}\) and \(\hat{\epsilon}\).
def plot_results(name, dates, y, yhat, ehat, std_yhat, std_ehat, sigma, alpha):
    '''Plot observations + fitted model, residuals and a histogram of the normalized residuals.'''
    k98 = norm.ppf(1-0.5*alpha)
    CI_e = k98 * std_ehat
    CI_yhat = k98 * std_yhat
    CI_label = f'{100 * (1 - alpha):.0f}% confidence region'
    fig = plt.figure(figsize=(14, 8))
    ax1 = plt.subplot2grid((2, 3), (0, 0), colspan=3)
    ax2 = plt.subplot2grid((2, 3), (1, 0), colspan=2)
    ax3 = plt.subplot2grid((2, 3), (1, 2))

    ax1.plot(dates, y, '.', color='k', ms=3, label='observations')
    ax1.plot(dates, yhat, color='tab:red', label='fitted model')
    ax1.fill_between(dates, yhat - CI_yhat, yhat + CI_yhat,
                     color='tab:red', alpha=0.3, label=f'CI yhat {100 * (1 - alpha):.0f}%')

    ax1.set_xlim(dates.iloc[0], dates.iloc[-1])
    ax1.set_ylabel('displacement [mm]')
    ax1.set_title(f'{name}: observations and fitted model')
    ax1.legend(loc='lower left')


    ax2.plot(dates, ehat, '.', color='k', ms=3)
    ax2.fill_between(dates, -CI_e, CI_e, color='tab:red', alpha=0.2,
                     label=f'CI ehat {100 * (1 - alpha):.0f}%')

    ax2.set_xlim(dates.iloc[0], dates.iloc[-1])
    ax2.set_ylabel('residual [mm]')
    ax2.set_title('residuals')
    ax2.legend(loc='lower left')

    ax3.hist(ehat / sigma, bins=30, density=True, color='lightgrey', edgecolor='k')
    xx = np.linspace(-4, 4, 200)
    ax3.plot(xx, norm.pdf(xx), color='tab:red', label='N(0,1)')
    ax3.set_xlabel('residual / sigma [-]')
    ax3.set_title('normalized residuals')
    ax3.legend()
    plt.tight_layout()
    plt.show()

    print(f'{name}: mean residual = {ehat.mean():.2f} mm, std residual = {ehat.std():.2f} mm '
          f'(sigma = {sigma} mm)')
plot_results('InSAR', dates_insar, y_insar, yhat_insar, ehat_insar,
             std_yhat_insar, std_ehat_insar, sigma_insar, alpha=0.02)
plot_results('Extensometer', dates_ext, y_ext, yhat_ext, ehat_ext,
             std_yhat_ext, std_ehat_ext, sigma_ext, alpha=0.02)
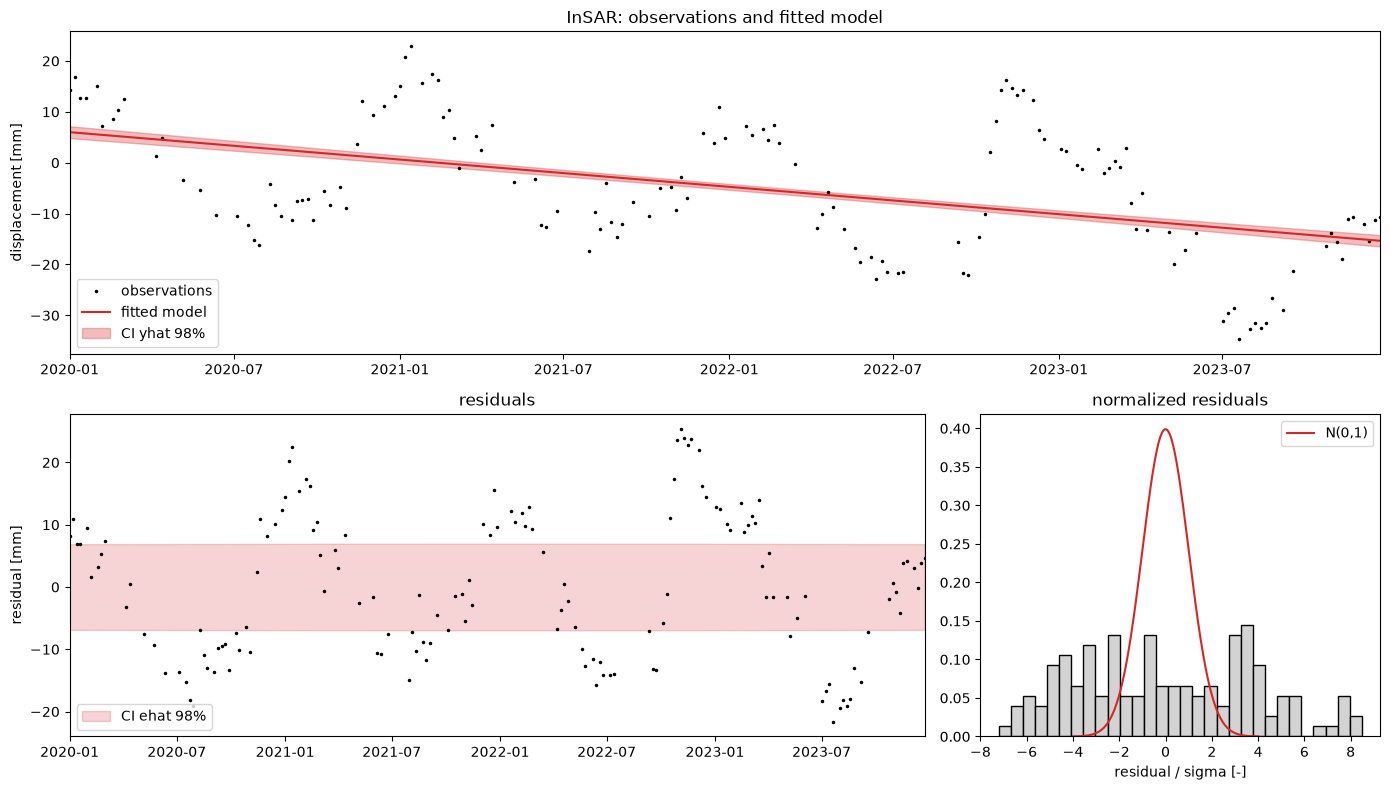
InSAR: mean residual = 0.00 mm, std residual = 11.50 mm (sigma = 3 mm)
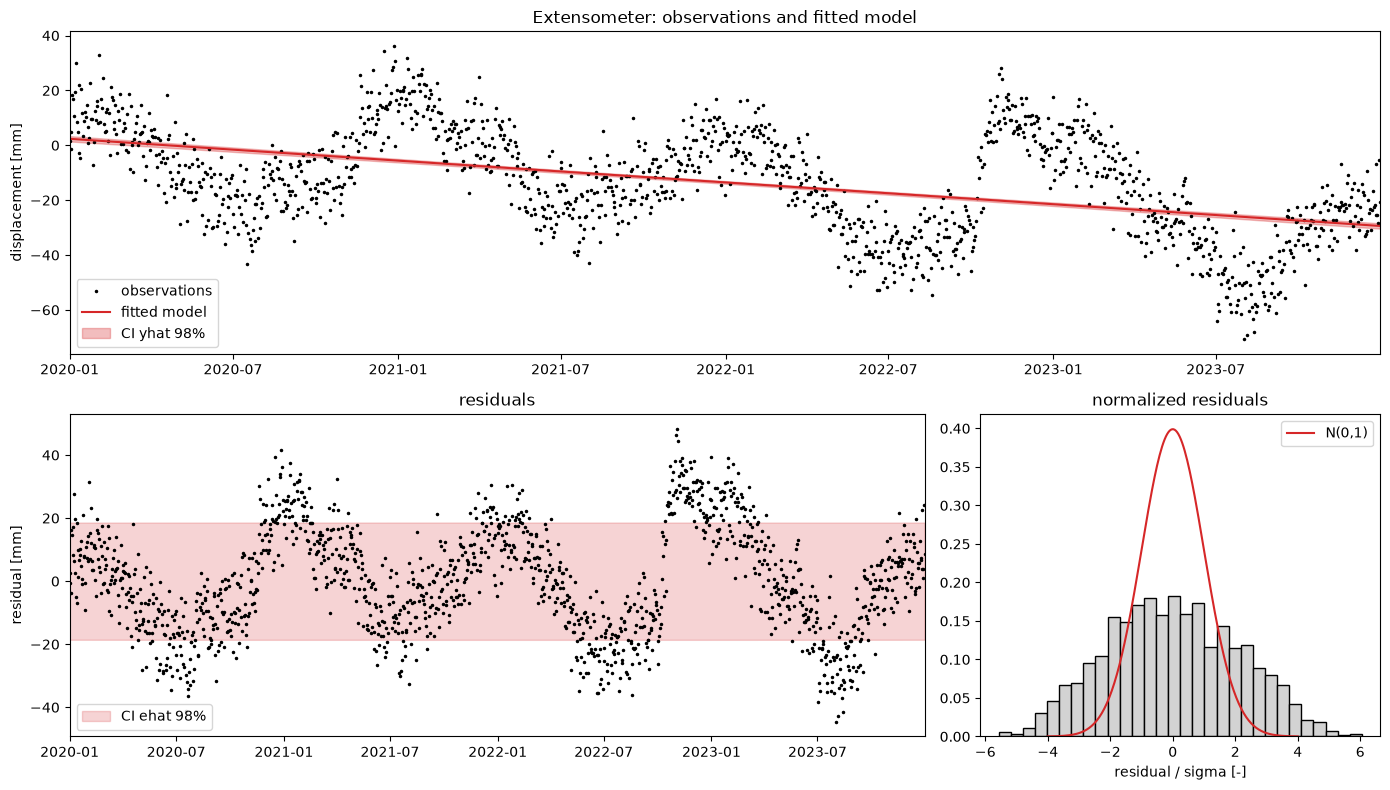
Extensometer: mean residual = -0.00 mm, std residual = 16.86 mm (sigma = 8 mm)
Task 5.3:
Write down your observations for each figure: the graphs of \(\hat{y}\) and \(\hat{e}\) and the distribution of the normalized residuals.
Part 6: A model driven by the weather (Model 2)#
In this part we build a model that uses the weather data to explain the surface movement, while keeping it linear, so that we can still use BLUE.
Lets check out the weather data (we loaded this already in the beginning of the notebook)
What is in weather.csv?#
The file contains one row for every day from 1 January 2019 to 31 December 2023. The weather starts one year before the first observation (1 January 2020). We explain why below.
Column |
Unit |
Meaning |
|---|---|---|
|
– |
calendar date |
|
days |
number of days since 1 January 2019 (day 0) |
|
mm/day |
precipitation \(P\): water that comes in (rain) |
|
mm/day |
evapotranspiration \(E\): water that goes out (evaporation from the soil + transpiration by the grass) |
|
– |
1 if the day is dry, 0 if it is wet (definition below) |
|
days |
\(D(t)\): the number of dry days counted from the start of the file up to and including that day |
The difference \(P - E\) [mm/day] is the net water input of the parcel. Positive means the parcel gets wetter that day; negative means it dries out.
Day shows the number of days since 1 January 2019 (starts at 0). So for an observation on day Day, the weather on that day is simply P[Day], D[Day], etc.
Two processes, two weather variables#
Lets introduce two processes that we think will affect the movement of peat ground. We describe each of them with a variable computed from the weather file.
1. Irreversible subsidence: the dry-day counter \(D(t)\)
Peat only oxidises when it is dry, so the ground only goes down on dry days. A day is dry when the net water input over the last few days (including that day) is zero or negative.
\(D(t)\) is the number of dry days up to day \(t\). It goes up by 1 on a dry day and stays the same on a wet day. You can find it in the column DryDays of the weather file.
The irreversible subsidence is then:
where \(x_I\) is the subsidence per dry day [mm/day]. This replaces the \(v\,t\) term of the linear trend.
2. Reversible motion: the water surplus \(S_\tau(t)\)
The soil swells when it gets wetter and shrinks when it dries out. How wet it is depends on today’s weather and also on the days and weeks before: the soil has a memory. We model this as a leaky bucket. Each day the net input \(P - E\) is added, and part of the old content leaks away:
\(S_i\) is the water surplus [mm] on day \(i\). Because each day depends on the day before, you compute it day by day. Start with an empty bucket on the first day of the weather record. We write it as \(S_\tau(t)\) because it depends on \(\tau\).
\(\tau\) [days] is the soil’s memory. Each day the bucket keeps a fraction \(e^{-1/\tau}\) of its content. For example, \(\tau = 10\) gives \(e^{-1/10} \approx 0.90\), so about 10% leaks away each day.
Small \(\tau\): the soil reacts fast and forgets fast.
Large \(\tau\): the soil reacts slowly and remembers longer.
The reversible motion is then:
where \(k\) [-] is a scaling factor.
Why does the weather data start one year earlier? We start the bucket empty on 1 January 2019, which is not the real state of the soil. After a year, the effect of that starting value is negligible. The dry-day counter also needs the previous days (we computed this already for you in DryDays). This first year is called the spin-up period.
The new functional model#
Combining both processes gives
In this assignment we fix \(\tau = 10\) days. Then \(D(t)\) and \(S_{10}(t)\) are known numbers for every day, and the three unknowns \(d_0\), \(x_I\) and \(k\).
Task 6.1:
Load the dry-day counter \(D\) from the column
DryDays[days]of the weather file.Complete the function
water_surplusbelow and compute the water surplus \(S\) with \(\tau = 10\) days for every day of the weather record.Plot both \(D(t)\) and \(S_{10}(t)\) for every day of the weather record
Then run the cell after it to plot \(S\) and \(D\).
weather
| Dates | Day | Precipitation[mm] | Evapotranspiration[mm] | Dry[-] | DryDays[days] | |
|---|---|---|---|---|---|---|
| 0 | 2019-01-01 | 0 | 4.2 | 0.1 | 0 | 0 |
| 1 | 2019-01-02 | 1 | 0.0 | 0.1 | 0 | 0 |
| 2 | 2019-01-03 | 2 | 1.8 | 0.1 | 0 | 0 |
| 3 | 2019-01-04 | 3 | 4.4 | 0.2 | 0 | 0 |
| 4 | 2019-01-05 | 4 | 0.0 | 0.1 | 0 | 0 |
| ... | ... | ... | ... | ... | ... | ... |
| 1821 | 2023-12-27 | 1821 | 0.0 | 0.1 | 0 | 667 |
| 1822 | 2023-12-28 | 1822 | 0.0 | 0.1 | 0 | 667 |
| 1823 | 2023-12-29 | 1823 | 0.1 | 0.1 | 0 | 667 |
| 1824 | 2023-12-30 | 1824 | 0.0 | 0.1 | 0 | 667 |
| 1825 | 2023-12-31 | 1825 | 0.0 | 0.1 | 0 | 667 |
1826 rows × 6 columns
D = weather['DryDays[days]'].to_numpy()

def water_surplus(P, E, tau):
    '''Leaky-bucket water surplus S [mm] for every day of the weather record.'''
    a = np.exp(-1 / tau)
    S = np.zeros(len(P))
    S_previous = 0.0
    for i in range(len(P)):
        S[i] = a * S_previous + (P[i] - E[i])
        S_previous = S[i]
    return S

tau = 10   # days (fixed)
S = water_surplus(P, E, tau)
fig, ax = plt.subplots(2, 1, figsize=(12, 6), sharex=True)
ax[0].plot(dates_weather, S)
ax[0].set_ylabel('S [mm]')
ax[0].set_title(f'Water surplus (tau = {tau} days)')
ax[1].plot(dates_weather, D, color='tab:orange')
ax[1].set_ylabel('D [days]')
ax[1].set_title('Number of dry days')
for a in ax:
    a.axvline(dates_insar.iloc[0], color='k', ls='--', lw=1, label='First observation')   # first observation
for a in ax:
    a.legend()
plt.tight_layout()
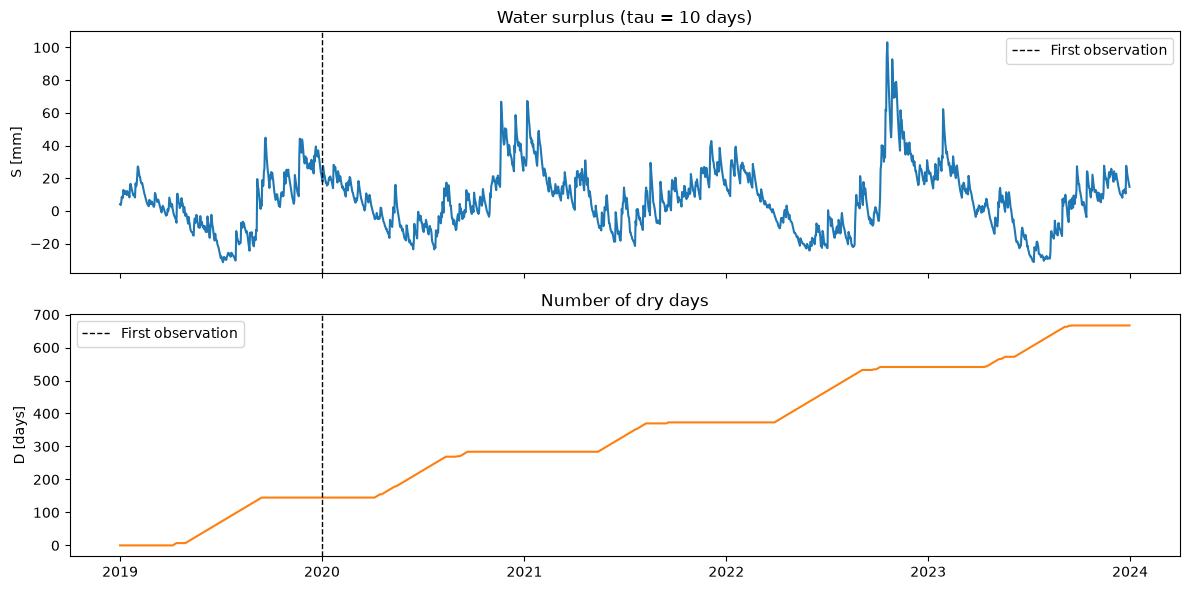
Task 6.2:
Describe the behavior of \(S\) and \(D\) over the year. (make a sketch of the plots)
Task 6.3:
Set up the design matrices
A2_insarandA2_extfor the new model and estimate the unknowns with yourBLUEfunction. Use the columnDay(same as you did for your design matrix for model 1) to pick the values of \(D\) and \(S\) on the observation days.
A2_insar = np.column_stack([np.ones(len(day_insar)), D[day_insar], S[day_insar]])
A2_ext = np.column_stack([np.ones(len(day_ext)), D[day_ext], S[day_ext]])

xhat2_insar, Sigma_Xhat2_insar = BLUE(A2_insar, y_insar, Sigma_Y_insar)
xhat2_ext, Sigma_Xhat2_ext = BLUE(A2_ext, y_ext, Sigma_Y_ext)

print("--InSAR--")
print("d0 = {:.4f} +/- {:.4f} mm".format(xhat2_insar[0], np.sqrt(Sigma_Xhat2_insar[0, 0])))
print("x_I = {:.4f} +/- {:.4f} mm/dry day".format(xhat2_insar[1], np.sqrt(Sigma_Xhat2_insar[1, 1])))
print("k = {:.4f} +/- {:.4f}".format(xhat2_insar[2], np.sqrt(Sigma_Xhat2_insar[2, 2])))
print()
print("--Extensometer--")
print("d0 = {:.4f} +/- {:.4f} mm".format(xhat2_ext[0], np.sqrt(Sigma_Xhat2_ext[0, 0])))
print("x_I = {:.4f} +/- {:.4f} mm/dry day".format(xhat2_ext[1], np.sqrt(Sigma_Xhat2_ext[1, 1])))
print("k = {:.4f} +/- {:.4f}".format(xhat2_ext[2], np.sqrt(Sigma_Xhat2_ext[2, 2])))
print()
print("InSAR Sigma_X2:\n", Sigma_Xhat2_insar)
print("Extensometer Sigma_X2:\n", Sigma_Xhat2_ext)
--InSAR--
d0 = 7.6950 +/- 0.7218 mm
x_I = -0.0422 +/- 0.0016 mm/dry day
k = 0.4632 +/- 0.0119

--Extensometer--
d0 = 5.8236 +/- 0.5909 mm
x_I = -0.0613 +/- 0.0014 mm/dry day
k = 0.6839 +/- 0.0107

InSAR Sigma_X2:
 [[ 5.210e-01 -1.080e-03 -1.514e-03]
 [-1.080e-03  2.623e-06  2.136e-07]
 [-1.514e-03  2.136e-07  1.406e-04]]
Extensometer Sigma_X2:
 [[ 3.492e-01 -7.385e-04 -9.713e-04]
 [-7.385e-04  1.829e-06  1.546e-07]
 [-9.713e-04  1.546e-07  1.154e-04]]
Task 6.4:
Compute the adjusted observations and residuals of the new model by calling your
get_resultsfunction, plot them withplot_results(plot again the 98% confidence level)
yhat2_insar, ehat2_insar, std_yhat2_insar, std_ehat2_insar = get_results(
    A2_insar, y_insar, Sigma_Y_insar, xhat2_insar, Sigma_Xhat2_insar)
yhat2_ext, ehat2_ext, std_yhat2_ext, std_ehat2_ext = get_results(
    A2_ext, y_ext, Sigma_Y_ext, xhat2_ext, Sigma_Xhat2_ext)

plot_results('InSAR (weather model)', dates_insar, y_insar, yhat2_insar, ehat2_insar,
             std_yhat2_insar, std_ehat2_insar, sigma_insar, alpha=0.02)
plot_results('Extensometer (weather model)', dates_ext, y_ext, yhat2_ext, ehat2_ext,
             std_yhat2_ext, std_ehat2_ext, sigma_ext, alpha=0.02)
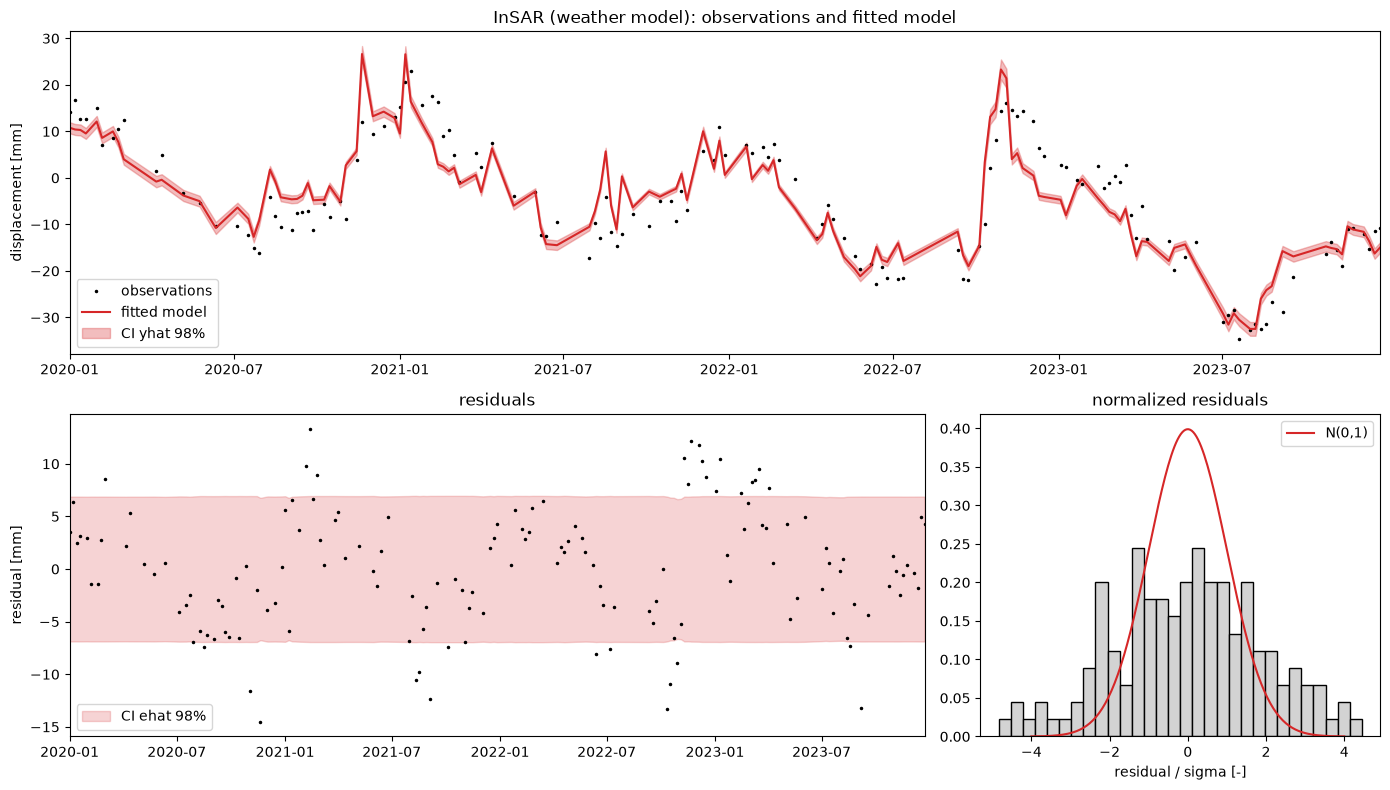
InSAR (weather model): mean residual = 0.00 mm, std residual = 5.72 mm (sigma = 3 mm)
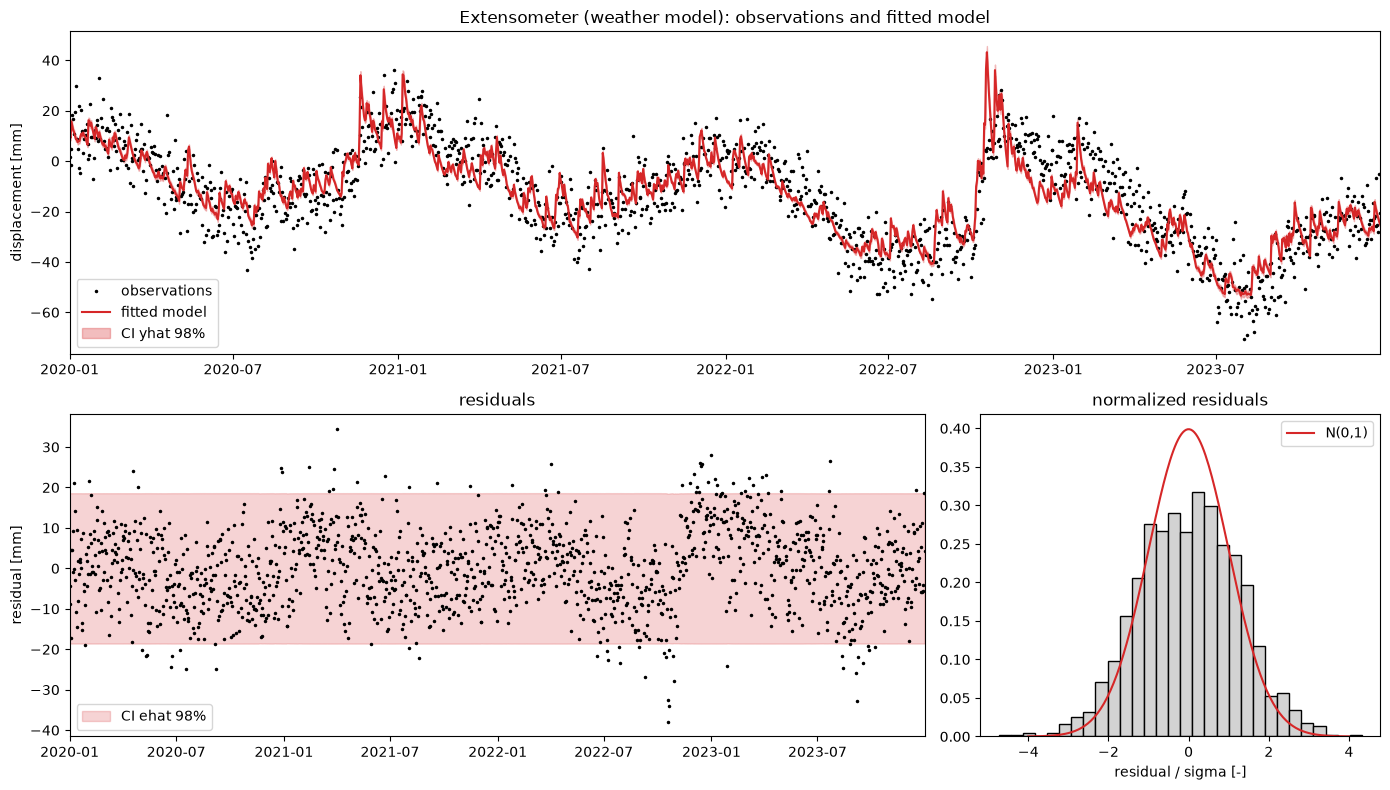
Extensometer (weather model): mean residual = 0.00 mm, std residual = 9.90 mm (sigma = 8 mm)
Task 6.5:
Interpret the estimated parameters. Convert \(x_I\) to mm/year (compute how many days per year on average the parcel has) and compare it with the velocity \(v\) from Part 4 (model 1).
Compare the estimated observations and residuals with those of model 1, compare the figures.
Note down your findings with pen and paper
# average number of dry days per year during the observation period (2020-2023)
first_day, last_day = day_ext[0], day_ext[-1]
years = (last_day - first_day) / 365.25
N_dry = (D[last_day] - D[first_day]) / years
print(f'average number of dry days per year: {N_dry:.1f}')


v_I_insar = xhat2_insar[1] * N_dry
std_v_I_insar = np.sqrt(Sigma_Xhat2_insar[1, 1]) * N_dry

v_I_ext = xhat2_ext[1] * N_dry
std_v_I_ext = np.sqrt(Sigma_Xhat2_ext[1, 1]) * N_dry

print('InSAR:')
print(f'  x_I * N_dry      = {v_I_insar:.2f} +/- {std_v_I_insar:.2f} mm/yr')
print(f'  v from Part 4    = {xhat_insar[1]:.2f} +/- {np.sqrt(Sigma_Xhat_insar[1, 1]):.2f} mm/yr')

print('Extensometer:')
print(f'  x_I * N_dry      = {v_I_ext:.2f} +/- {std_v_I_ext:.2f} mm/yr')
print(f'  v from Part 4    = {xhat_ext[1]:.2f} +/- {np.sqrt(Sigma_Xhat_ext[1, 1]):.2f} mm/yr')
average number of dry days per year: 130.6
InSAR:
  x_I * N_dry      = -5.52 +/- 0.21 mm/yr
  v from Part 4    = -5.37 +/- 0.21 mm/yr
Extensometer:
  x_I * N_dry      = -8.01 +/- 0.18 mm/yr
  v from Part 4    = -7.95 +/- 0.18 mm/yr
Do a double check and make sure you wrote all your findings down with pen and paper, so that you can discuss or refer to them when answering the questions in the report
Solution 6.5:
InSAR: \(x_I = -0.042 \pm 0.002\) mm/dry day, \(k = 0.46 \pm 0.01\). Extensometer: \(x_I = -0.061 \pm 0.001\) mm/dry day, \(k = 0.68 \pm 0.01\). With about 131 dry days per year, this corresponds to \(-5.5 \pm 0.2\) mm/yr (InSAR) and \(-8.0 \pm 0.2\) mm/yr (extensometer), close to the velocities from Part 4 (\(-5.4\) and \(-7.9\) mm/yr). Both models describe a similar long-term subsidence rate, but the new model says when it happens: only during dry periods. The extensometer spot subsides faster and also swells/shrinks more (larger \(k\)) than the parcel average, consistent with a wetter, peatier spot.
The seasonal pattern has largely disappeared from the residuals although you can still see a bit of a pattern, and the histogram of the normalized residuals is much closer to N(0,1), although still too wide. The weather model is a large improvement, but it is not yet complete. The most likely cause is the fixed \(\tau = 10\) days: the soil memory is a property of the soil and there is no reason why it should be 10 days, or the same for the parcel average and the extensometer spot. Estimating \(\tau\) from the data requires a non-linear estimation method, which is the topic of next week.
By
Isabel Slingerland, Delft University of Technology. CC BY 4.0, more info on the Credits page of Workbook.